Social media data, built for AI training
The social data your AI model is missing.
500M+ social media posts, 400B+ post reactions, 100M+ brand logos, and 50M+ spotted objects. Built over years by our PhD-led AI team. The most comprehensive digital dataset for sports and entertainment.
datastore/sample-preview
- txt-001InstagramTextWhat a match! @realmadrid absolutely dominated tonight. Vinicius Jr. with the hat trick...Text#LaLiga #RealMadrid #Football
- img-001InstagramImageStadium aerial view during Champions League final with full crowd, banner overlays, LED boards showing sponsor logosImageHeineken, PlayStation, Adidas · 12 boxes
- txt-002X / TwitterTextThe NBA Finals Game 7 ratings just came in — 28.7M viewers. Basketball is back.Text#NBA #NBAFinals #Basketball
- vid-001TikTokVideoHighlights from the championship match with player reactions and crowd momentsVideo2:34 · 3 scenes · captions
- img-002X / TwitterImagePost-game celebration photo with players wearing jerseys showing sponsor patches — front, sleeve, and backImageEmirates, Adidas, EA Sports · 8 boxes
Free sample · up to 10K records per category
Request a curated dataset- Social media posts
- 500M+
- Post reactions tracked
- 400B+
- Brand logos detected
- 100M+
- Spotted objects
- 50M+
[01] Datasets
Five modalities. One comprehensive platform.
500M+ posts, 400B+ reactions, 100M+ logos, 50M+ objects. Built over years by our PhD-led AI team with proprietary computer vision. The most comprehensive digital dataset for sports and entertainment.
- 01
Text
Social and digital text data from leagues, teams, players, and sponsors in sports and entertainment. Includes captions, comments, hashtags, and conversation threads spanning back to 2014.
For LLM training in sports & entertainment
- Volume
- 500M+ posts
- Formats
- JSONParquetCSV
- 02
Image
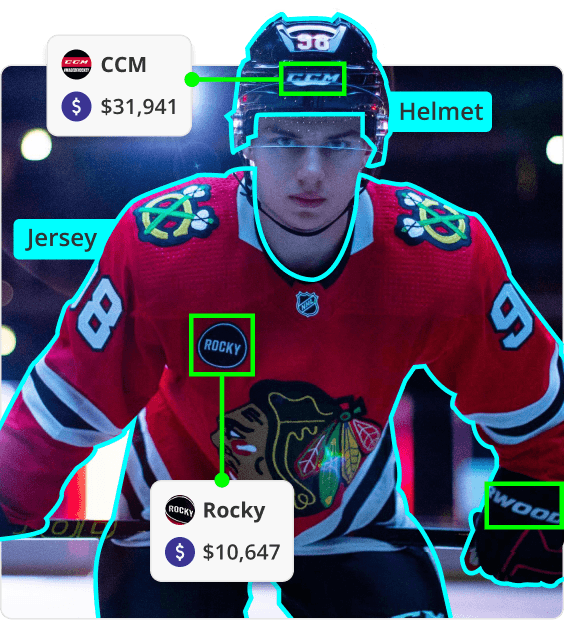
High-resolution social images with brand logo detection, scene context, and multimodal alignment. Includes 100M+ verified brand logo samples with our proprietary computer vision engine.
Rich multimodal LLM data
- Volume
- Multimodal pairs
- Formats
- WebDatasetJSONL + URLs
- 03
Video
Short and long-form social video with transcripts, scene segmentation, and OTT viewership data. Years of anonymized OTT data including retention graphs and brand valuations per time slice.
OTT content with retention metrics
- Volume
- 45M+ clips
- Formats
- WebDatasetHF Datasets
- 04
Annotated
50M+ spotted objects including bounding boxes, brand logos, jersey numbers, and sponsor placements. Human-verified object detection built by our PhD-led AI team with patented computer vision engine.
Proprietary computer vision data
- Volume
- 50M+ objects
- Formats
- COCOPascal VOCJSONL
- 05
Broadcast
Live broadcast frames with OCR-extracted text from overlays, tickers, and scoreboards. Real-time tracking across 40+ sports, 170+ professional leagues, 2,800+ teams, 150,000+ players, and 1,800+ brands.
40+ sports, 170+ leagues tracked
- Volume
- Real-time tracking
- Formats
- ParquetTFRecord
[02] Sample data
Rich, structured data. Not noisy web scrapes.
Every record is deeply annotated — entities extracted, sentiment scored, engagement metrics attached, brands detected. This is the data quality your training pipeline actually needs.
- Fields per record
- 40+
- Data modalities
- 5
- Fresh data refresh
- Daily
Rendered
What a match! @realmadridteam absolutely dominated tonight. Viniciusplayer with the hat trick, Bellinghamplayer controlling the midfield. This team is different. #LaLiga #HalaMadrid
- Real Madridteam0.99
- Vinicius Jr.player0.97
- Jude Bellinghamplayer0.95
- Language
- en
- Sport
- football
- League
- La Liga
Raw record
1{2 "id": "txt-384291",3 "platform": "instagram",4 "timestamp": "2025-12-14T18:32:00Z",5 "content": "What a match! @realmadrid absolutely dominated tonight. Vinicius with the hat trick, Bellingham controlling the midfield. This team is different. #LaLiga #HalaMadrid",6 "author": { "follower_count": 48200, "verified": false, "account_type": "fan" },7 "entities": [8 {9 "text": "Real Madrid",10 "type": "team",11 "span": [14, 25],12 "confidence": 0.9913 },14 {15 "text": "Vinicius Jr.",16 "type": "player",17 "span": [56, 64],18 "confidence": 0.9719 },20 {21 "text": "Jude Bellingham",22 "type": "player",23 "span": [85, 95],24 "confidence": 0.9525 }26 ],27 "hashtags": ["#LaLiga", "#HalaMadrid"],28 "language": "en",29 "sport": "football",30 "league": "La Liga"31}[03] Use cases
Your model is only as good as its training data.
Whether you're building a frontier model, a trading signal, or a prediction engine — social media data is the layer you're missing.
The problem
Sports and entertainment organizations need real-time insights across multiple social platforms and hundreds of stakeholders.
Our data
Our AI tracks social posts from rights holders, teams, leagues, brands, and players across 7+ platforms in near real-time. 40+ sports, 170+ professional leagues, 2,800+ teams, 150,000+ players tracked daily.
- Text Data
- Real-time Tracking
- Engagement Analytics
[04] Why Blinkfire AI
Everyone claims to have data. We prove it.
Not scraped. Earned.
We don't scrape public feeds. Blinkfire has direct data partnerships across 150+ sports and entertainment properties. This is first-party, licensed data.
Human + ML annotated.
Every dataset goes through our proprietary annotation pipeline — computer vision for detection, human reviewers for quality. 99.4% accuracy, verified.
Updated continuously.
Social data moves fast. Our datasets are refreshed daily with new content, engagement signals, and trend annotations. Your model stays current.
Compliance-ready.
All data is PII-scrubbed, GDPR-compliant, and delivered with full provenance documentation. Enterprise-grade licensing for model training.
[05] FAQ
Questions about our training data.
What is Blinkfire AI?
Blinkfire AI licenses annotated, multimodal training data for AI models in sports and entertainment: 500M+ social media posts, 400B+ post reactions, 100M+ detected brand logos, 50M+ spotted objects, 45M+ video clips and live broadcast data, spanning back to 2014. It is built by the PhD-led AI team whose technology also powers Blinkfire Analytics.
What kinds of AI training data does Blinkfire AI offer?
Five modalities: text (captions, comments, hashtags and conversation threads), image (social images with brand logo detection and scene context), video (short and long-form video with transcripts, scene segmentation and OTT viewership data), annotated data (bounding boxes for brand logos, jersey numbers and sponsor placements) and broadcast (frames with OCR text from overlays, tickers and scoreboards).
Is the data scraped?
No. Blinkfire has direct data partnerships across 150+ sports and entertainment properties, so the data is first-party and licensed. Every dataset goes through a proprietary annotation pipeline, with computer vision for detection and human reviewers for quality, at 99.4% verified accuracy.
Can I use Blinkfire data to train commercial models?
Yes. All data is PII-scrubbed, GDPR-compliant and delivered with full provenance documentation under enterprise licensing for commercial model training.
Is there a free sample?
Yes. You can request a free sample of up to 10K records in any category, with no commitment. Custom datasets can be filtered by sport, league, platform, timeframe or engagement threshold.
What formats is the data delivered in?
JSON, JSONL, Parquet, CSV, WebDataset, Hugging Face Datasets and TFRecord, plus COCO and Pascal VOC for object annotations.
How much history and coverage does the data have?
Data spans back to 2014 and is refreshed daily. Coverage includes 40+ sports, 170+ professional leagues, 2,800+ teams, 150,000+ players and 1,800+ brands across 7+ social platforms.
How is Blinkfire AI different from Mercor, micro1 or Scale AI?
Mercor, micro1 and Scale AI are best known for supplying human experts and labelers who create or label training data on demand. Blinkfire AI licenses data that already exists: more than a decade of real social, video and broadcast data from sports and entertainment, already annotated by computer vision and human reviewers. Teams choose Blinkfire when they need real-world, domain-specific coverage at scale right away, and can still pair it with expert labeling for custom tasks.
What can I build with Blinkfire training data?
Multimodal LLMs that understand sports and entertainment, logo detection and sponsorship valuation models, broadcast OCR and overlay detection, real-time social tracking, and historical sponsorship ROI analysis.
[06] Get started
The best AI teams are training on social data. Are you?
The models that win will be the ones with the best training data — not just more of it. Blinkfire AI gives you the signal in a sea of noise.
Your next model deserves better data.
Stop training on noisy web scrapes. Get access to the largest annotated social media dataset built specifically for AI training.
- 01
Free sample available. Up to 10K records across any category — no commitment required.
- 02
Custom datasets. Filter by sport, league, platform, timeframe, or engagement threshold.
- 03
Enterprise licensing. Full provenance, GDPR-compliant, ready for commercial model training.